Two providers can advertise the same model and still produce different bills. GLM 5.3 Flash pricing depends on endpoint, token categories, caching, and routing. A low headline rate is not enough to establish the cheapest provider for your workload.
This article is based on the official Z.ai pricing page, Flash model card, and GLM5 model documentation reviewed November 13, 2026. It replaces an unsupported multi-provider ranking with a reproducible quote-comparison method. No eight-provider live performance test is claimed.
GLM 5.3 Flash pricing at the original provider
| Token category | Direct Z.ai rate per million tokens |
|---|---|
| Fresh input | $0.15 |
| Cached input | $0.03 |
| Output | $0.50 |
These figures belong to the direct API schedule. Another provider may expose a different price, capacity limit, or billing unit. Keep any promotional quote dated and separate from the standard schedule. The model card establishes model identity; the endpoint's billing page establishes what you pay.
Work through an example before comparing quotes
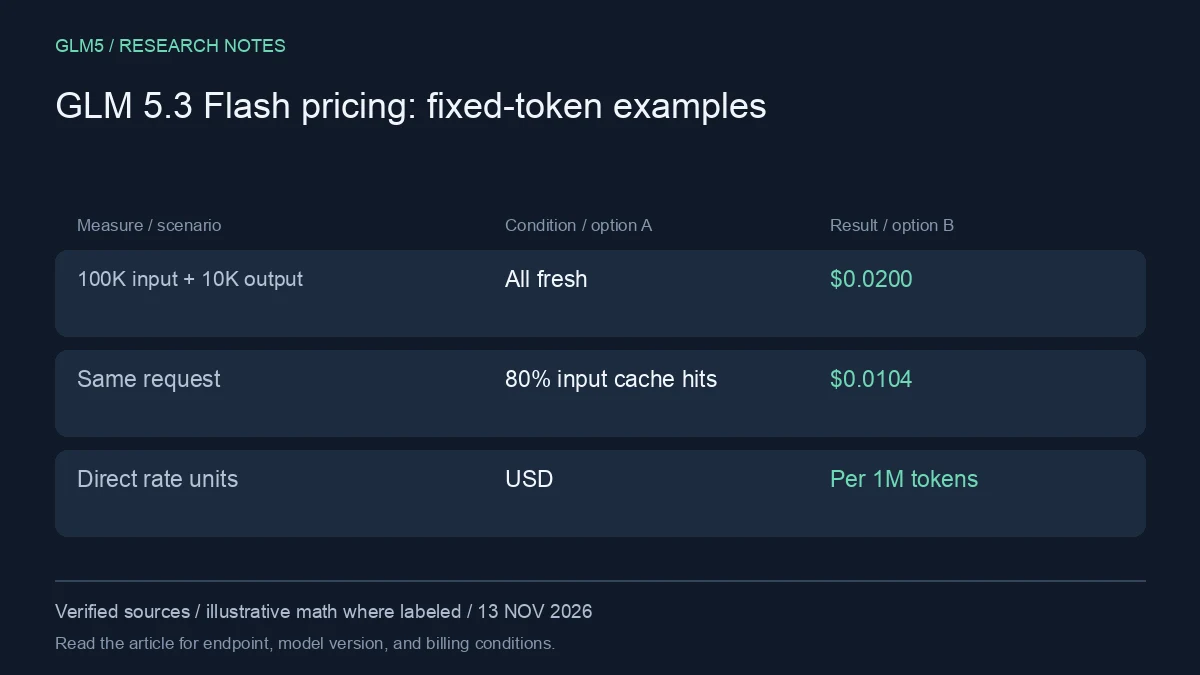
A request with 100,000 fresh input tokens and 10,000 output tokens costs $0.020 at the listed direct rates: $0.015 input plus $0.005 output. If 80% of the input is billed as cache hits, the input cost becomes $0.0054 and the total becomes $0.0104.
At 1,000 such requests, the illustrative totals are $20 and $10.40. These examples exclude other fees and assume a fixed output length. GLM 5.3 Flash pricing is attractive on this request shape, but a model that generates more tokens or requires retries may change the accepted-task total.
A provider quote worksheet
| Field to record | Why you need it |
|---|---|
| Exact model and served version | Similar names can route differently |
| Fresh input, cache read, cache write, output | One number cannot describe the full bill |
| Context and output limits | Model capacity and endpoint limits can differ |
| Rate limits and concurrency | A low price may not meet your deadline |
| Failure and retry billing | Repeated attempts affect total spend |
| Region, retention, and terms | Operational requirements may eliminate a quote |
| Quote date and promotion expiry | Temporary discounts need an end condition |
Do not fill missing rows with assumptions. Ask the provider or run a bounded test. If a provider publishes only a blended rate, document its assumed input/output mix before comparing it with category prices.
Keep throughput separate from price
The Flash model card describes multimodal input and an architecture designed for efficiency. That does not establish the latency or concurrency available to your account. Measure first useful output, full completion, errors, and retries on the same request shapes used for your cost worksheet.
A GLM 5.3 Flash pricing comparison should reject a cheap route if it fails required output or service constraints. Conversely, do not pay a premium solely because one isolated response arrived faster. Test the tail behavior under the concurrency you expect to use.
How GLM5 quotes differ
GLM5 lists glm-5.3-flash in its credit-based model catalog and describes Ox Alpha as a legacy preview alias. New integrations should use the documented current model ID. Read the current rate card and billing rules, rather than multiplying direct Z.ai dollars by an assumed conversion.
For a modest trial, send a representative task in Chat or follow the API guide. Record usage before expanding volume. Compare the result with a direct provider using the same acceptance conditions and source material.
Archive the quote and usage records together. That makes a future price change distinguishable from an increase in generated tokens, cache misses, or repeated attempts.
FAQ
Is Flash exactly ten times cheaper than the flagship?
Not in every category. At the listed direct schedules, fresh input differs by about 9.3 times and output by 8.8 times. The final ratio depends on token mix, cache hits, and retries.
Does a one-million-token model context guarantee that every provider accepts it?
No. Check the endpoint's request limits, reserved output space, and any account restrictions. A model capability and a service limit are distinct.
Which quote should I choose?
Choose the lowest total cost that meets your quality, latency, and operating requirements. GLM 5.3 Flash pricing should be evaluated with a dated worksheet and real usage records, not an undated ranking.
Sources
- Z.ai official API pricing
- GLM 5.3 Flash model card
- GLM5 API model IDs and credit rates
- GLM 5.3 model documentation
Source review: November 13, 2026. Prices and allowances are snapshots. Calculations in this article are illustrative, not measured production bills. GLM5 is the publisher of this article and a separate service from Z.ai.